PgConf.Russia 2019
PGConf.Russia is a leading Russian PostgreSQL international conference, annually taking together more than 500 PostgreSQL professionals from Russia and other countries — core and software developers, DBAs and IT-managers. The 3-day program includes training workshops presented by leading PostgreSQL experts, more than 40 talks, panel discussions and a lightning talk session.
Thems
- PostgreSQL at the cutting edge of technology: big data, internet of things, blockchain
- New features in PostgreSQL and around: PostgreSQL ecosystem development
- PostgreSQL in business software applications: system architecture, migration issues and operating experience
- Integration of PostgreSQL to 1C, GIS and other software application systems.
Talks
Talks archive
-
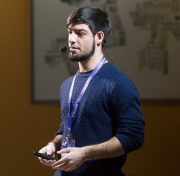 Artemy Ryabinkov Avito
In my talk I'll tell you about practices of working with Postgres in the Go-services. I’ll describe general advantages and disadvantages of the basic tools that are commonly used when working with Postgres using Go. Of course, we will touch on the nuances that need to be taken into account when your services are running inside the Kubernetes. I will also talk about Avito’s experience in providing a database of product’s developers. This presentation will be of interest to developers who want to avoid problems when working with Postgres, and will be useful to DBA who want to know what difficulties customers face in their database.
-
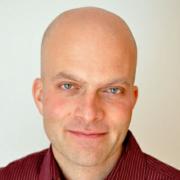 Miroslav Šedivý solute GmbH
So you finally have your database model for your application and you fill it in with current data. How do you keep it up to date? While INSERT may still be transparent, UPDATE and DELETE will overwrite your previous data, so you won't be able to reproduce them. Cloning the whole huge content for each minor update is not an option. For rich and complex data about hundreds of thousands of power generators in Germany and worldwide, I built a model using range data types in recent PostgreSQL which allows me to insert, update and delete data while granting the full access to the whole state of the database at any historical moment. I'll present a very simplified version of the database so the audience will be immediately able to apply it for their cases. I'll also show a few tricks in Python and Psycopg2 that will allow a whole team to prepare, review, and deploy all revisions to this database without merge conflicts. And I'll give a few ideas on how to retrieve this data efficiently.
-
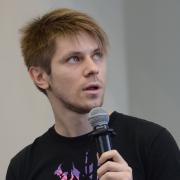 Aleksander Kuzmenkov PostgresPro
A major responsibility of a database engine is to convert a declarative SQL query to an efficient execution plan, employing various methods to scan and join the relations. There is always a development effort to improve this area. What clever execution plans can PostgreSQL generate, what's new in version 11 and what is in development? To name a few things, the joins are optimized by removing unneeded outer and inner joins, and reducing joins from outer and semi to inner. There is work to enable merge joins on inequality and range overlap, and to improve join selectivity estimates with multi-column statistics. When it comes to scanning a single relation, covering indexes allow to use index-only scans more often. Incremental sort and more precise estimation of sorting costs help generate better paths when sorted output is required, e.g. when using GROUP BY and ORDER BY or performing merge joins. This talk aims to give an overview of such optimizations that already exist and that are being developed now.
-
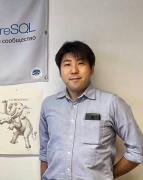 Tatsuro Yamada NTT Comware
As is often seen in OLAP and batch processing workloads, the more complex a query (containing many joins, filters, aggregates), the more there is a possibility of row count estimation errors, which leads to planner choosing an inefficient execution plan.
To address that problem, I developed a tool called pg_plan_advsr as a PostgreSQL extension, which corrects the estimation errors by repeatedly feeding back the information collected during query execution to the planner.
The tool has three features:
- Automatic plan tuning by repeatedly feeding execution information to planner
- Preserve all plans generated during plan tuning in a history table
- Create and store optimizer hints to be able to reproduce plans generated during tuning process
I verified the effectiveness of pg_plan_advsr by enabling it when running the join order benchmark (JOB) against PG 10.4 and observed its execution time shortening to 50% of the original. Therefore, it is useful for user who would like to do plan tuning for OLAP and batch processing.
I will talk about the following things in this presentation:
- Principles behind pg_plan_advsr and its architecture
- Detailed information about the measurements done with JOB
- Possible future enhancements
- Using aqo and pg_plan_advsr together (experimental)
Photos
Photo archive